Free Text to Video AI: Type a Prompt, Get a Video on VEO 3.1, Seedance 2.5 or Kling 3.0
The VdoBloom Text to Video Generator is an AI tool that converts a written prompt into a finished video clip. You type a description of the scene — subject, action, camera movement, lighting — and the AI renders it as motion footage. No source images or editing skills are needed, and new accounts get 10 free credits with no card so you can test a prompt before paying anything.
What sets VdoBloom apart is model choice. The same prompt can be sent to Google VEO 3.1, Seedance 2.5, Kling 3.0 Omni, Runway Gen-4.5, Wan 3.0, PixVerse v6, Hailuo and Grok Imagine from one box, so you can match the model to the job: VEO 3.1 for cinematic realism with native audio, Seedance 2.5 for physical motion and multi-shot scenes, Kling 3.0 Omni for spoken dialogue and lip-sync, Wan 3.0 when you want the most clips per credit. The credit cost of the exact model and settings is shown before you generate.
Prompts that work read like a shot list, not a mood board. Lead with who or what is in frame and what they are doing, then the camera move — slow dolly-in, handheld tracking, crane up — then lighting and setting. Multi-shot clips hold character identity best when each shot asks for one thing. If a result is close but wrong, change one element and regenerate; on the same credits you can send the identical prompt to a second model to compare, which single-model tools cannot do.
Output is a downloadable MP4 with commercial rights and no watermark on paid plans. Clip length and resolution depend on the model — Seedance 2.5 renders up to 30 seconds in one pass, VEO 3.1 favours short cinematic shots, Kling 3.0 Omni produces 15-second multi-shot scenes with synchronized speech — and every model page lists its limits, credit cost and real example outputs.
Examples
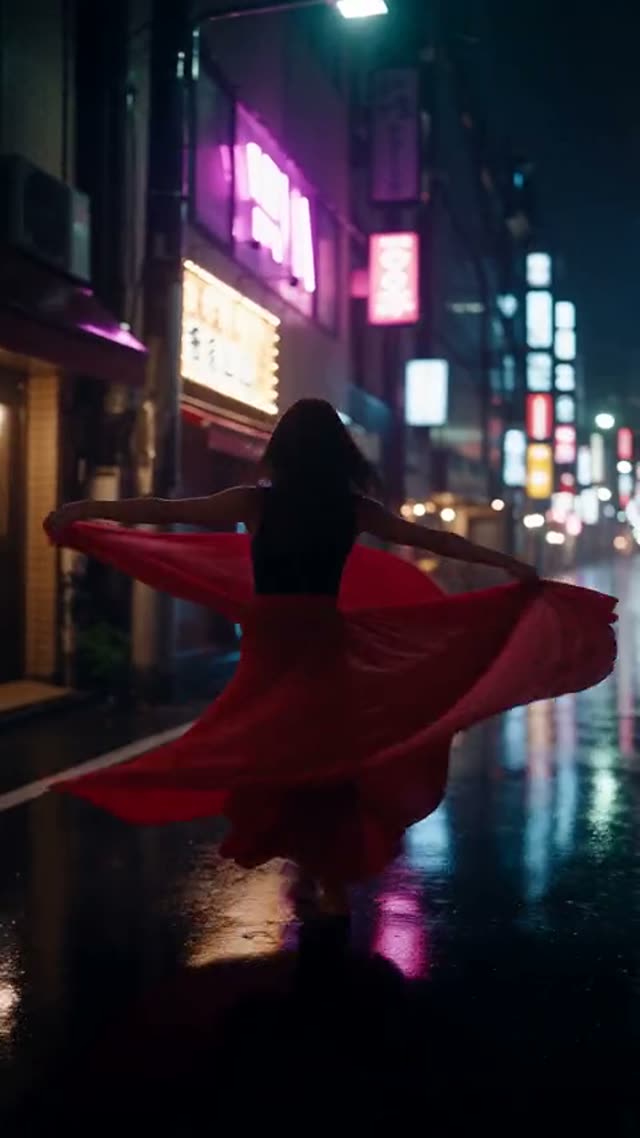
Seedance 2.5
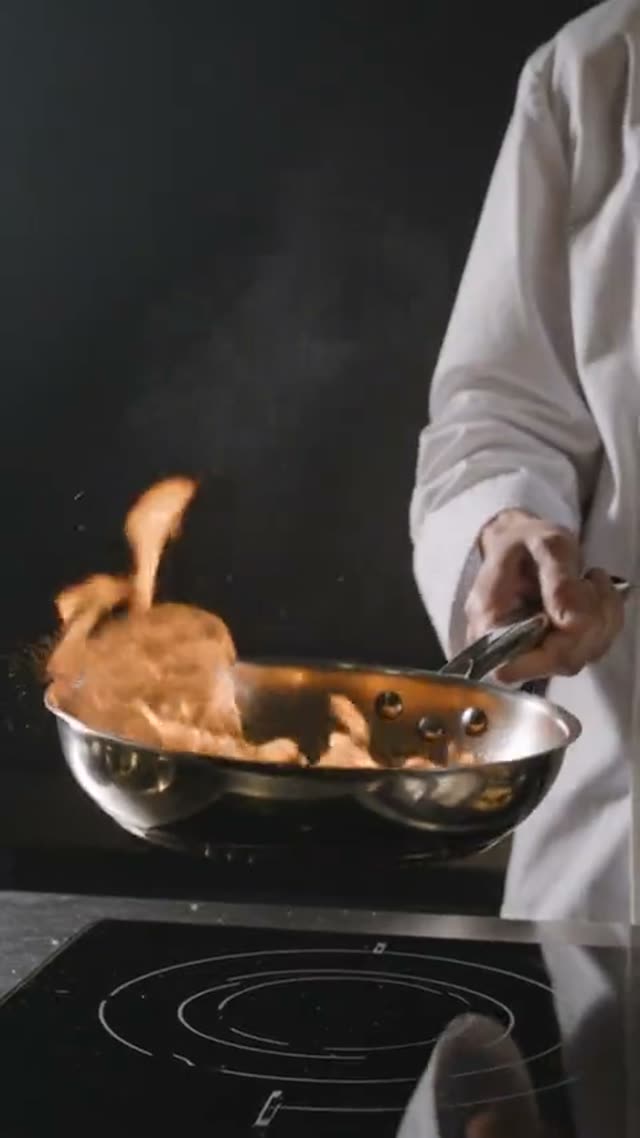
Kling V3.0 Omni Text-to-Video
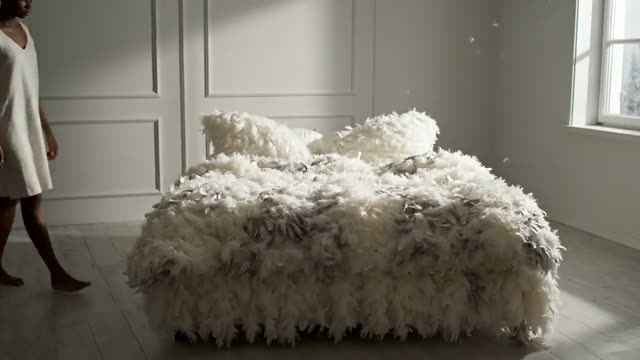
Veo 3.1 High Quality
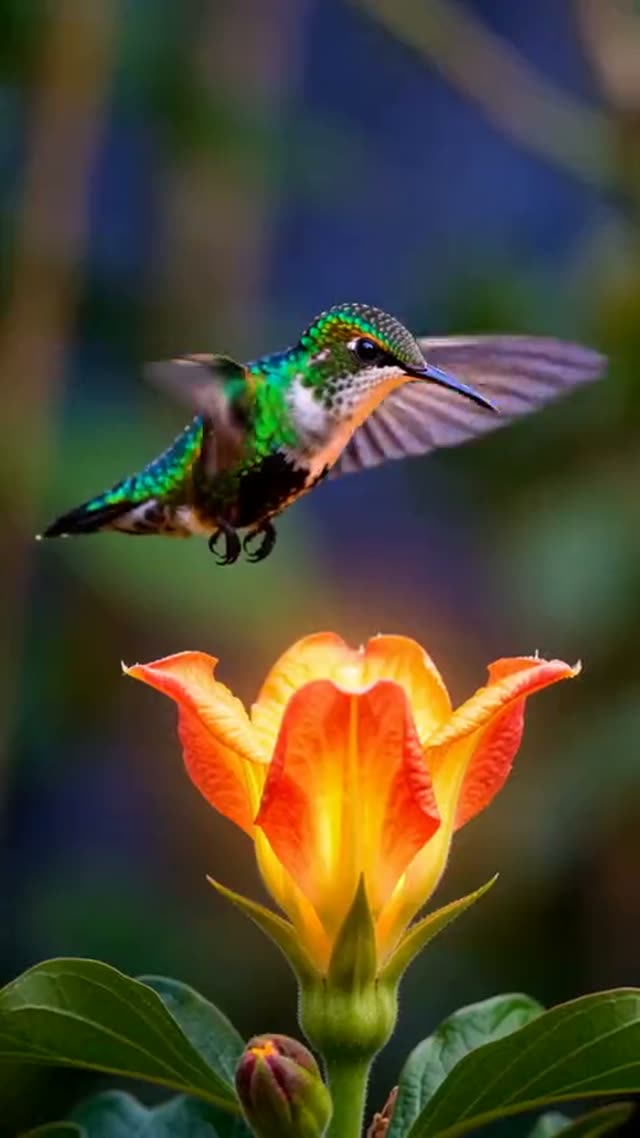
Wan AI 3.0 Video
How it works
- 1
Write your prompt
Describe the scene in detail — who or what is in frame, what happens, and the visual style you want.
- 2
Pick a model and settings
Choose from models like VEO 3.1, Runway, Kling, or Wan, then set aspect ratio and other options.
- 3
Generate
The AI renders your clip, typically within a few minutes depending on the model.
- 4
Download or refine
Save the result, or adjust your prompt and regenerate until the shot matches your vision.
Why use this tool
Nine frontier models in one prompt box
VEO 3.1, Seedance 2.5, Kling 3.0 Omni, Runway Gen-4.5, Wan 3.0, PixVerse v6, Hailuo, Grok Imagine — no separate accounts or API keys.
Free to start, priced per clip
10 free credits on sign-up. Then subscriptions from $15/month or one-time packs from $2.49 that never expire. Cost shown before every generation.
Flexible content filtering
Models are labelled by filter strictness. Dance, swimwear, fitness and fashion prompts that mainstream tools refuse generate on the flexible tier.
Prompt library with results
6,000+ Seedance prompts, each with the clip it produced — copy one, or load it straight into this tool.
Frequently asked questions
Which AI models can I use for text to video on VdoBloom?
VdoBloom gives you access to multiple leading text-to-video models in one place, including Google VEO 3.1, Runway, Wan, Seedance, and PixVerse. Each has different strengths — some favor photorealism, others speed or stylized output — so you can pick per project instead of committing to a single provider.
How do I write a good text-to-video prompt?
Describe the subject, the action, the setting, and the camera behavior in concrete terms — for example, the shot type, lighting, and mood. Specific prompts outperform vague ones. If a result is close but not right, change one element at a time and regenerate rather than rewriting the whole prompt.
How long does text-to-video generation take?
Most generations finish within a few minutes, though the exact time varies by model and settings — faster model variants trade some quality for speed, while high-quality modes take longer. You can queue a generation and keep working elsewhere in VdoBloom while it renders.
Is there a free text to video AI option?
Yes. Every new VdoBloom account gets 10 free credits with no card, usable on any text-to-video model including VEO 3.1, Seedance 2.5 and Kling 3.0 Omni. Paid plans start at $15/month for 300 credits, and one-time packs from $2.49 never expire. Current pricing is on the VdoBloom pricing page.
Do text-to-video downloads have a watermark?
Not on paid plans or credit packs — every model downloads clean with commercial rights. Free credits are for testing a prompt and model before you spend.
Which text-to-video model is the most realistic?
For cinematic realism with native sound, Google VEO 3.1. For believable physical motion, multi-shot scenes and the most flexible content filtering, Seedance 2.5. For clips that need spoken dialogue with lip-sync, Kling 3.0 Omni. Each model page on VdoBloom shows real example outputs so you can judge before spending credits.
Can I use the videos commercially?
Yes. Videos generated on paid plans and credit packs carry commercial rights. You are responsible for holding rights to any reference images you upload and for consent from any real person shown.